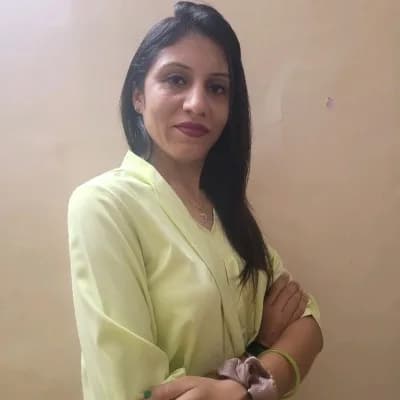
Swati Tyagi
Senior Full Stack and Mobile App Developer
Learn machine learning by building it — the full workflow from data and feature engineering to model tuning and deploying models to production.

A structured curriculum with real tools and outcomes built for the workplace.
Every instructor here ships production code for a living and teaches the same week they deploy.
5 learners sharing their experience
Browse the common questions, or reach out and our team will help you directly.
6 courses in this collection
 DevOps & Automation Bootcamp Beginner5 Months (20 Weeks)
 Java Full Stack Bootcamp with DSA & System Design Beginner6 Months (24 Weeks)
 Cybersecurity (SOC OPS, Cloud Security) Beginner4 Months (16 Weeks)
 Artificial Intelligence Bootcamp Beginner5 Months (20 Weeks)
 Forward Deployed Engineering (FDE) Masterclass Beginner20 weeks
 MERN Bootcamp with Microservices DSA & System Design Beginner6 Months (24 Weeks)
 Trending
 Trending
 Best seller
 Best seller
 Best seller
 Best seller
Hands-on programming tracks with runnable code, from fundamentals to job-ready projects.
 Docker Tutorial — Learn Docker from Scratch | Squarebrackets Intermediate15 Hours
 Kubernetes Beginner to Production Grade: A Hands-On DevOps Guide Beginner25 min
 100 Days of DSA with Java Beginner to advanced100 days · 85 lessons published
 100 Days of AI Engineering Beginner to advanced100 days · 57 lessons published
Articles to help you learn, grow, and get hired.
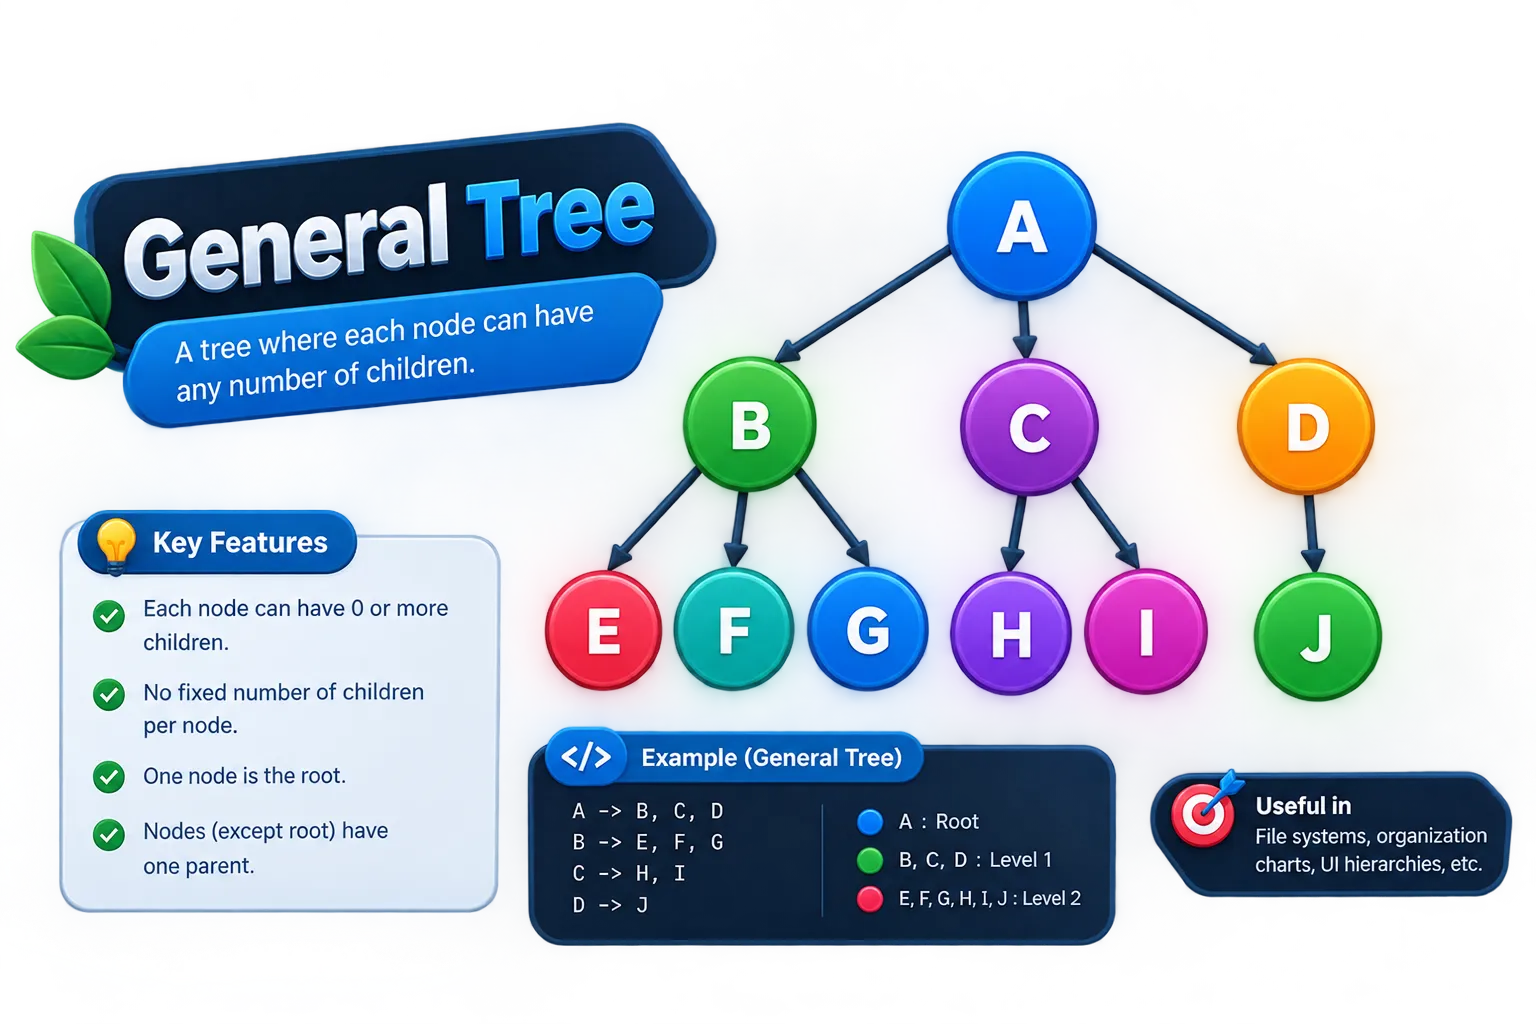 Generic Tree Interview Questions: Roadmap by Core Coding Techniques 5 min6 Sept 2026
 DSA Roadmap: Master Algorithms Roadmap 5 min5 Sept 2026
 Linked List Placement Preparation Roadmap: 15 Patterns with LeetCode 5 min1 Sept 2026
 Hashing in DSA: What Tech Interviews Actually Ask 5 min30 Aug 2026
 Placement Array Roadmap: The Ultimate Coding Interview Guide 5 min30 Aug 2026 Trending
Master N-ary and generic tree interview questions. This technical roadmap breaks down traversal, serialization, and recursion techniques with real-world coding patterns.
The ultimate master algorithm roadmap for our DSA roadmap. Learn the core patterns, time complexities, and coding techniques you need to crack FAANG interviews.
TrendingMaster linked list interview questions with our 15-step placement preparation roadmap. Features pattern breakdowns, practical code, and direct LeetCode links.
TrendingMaster hashing, HashMaps, and Map data structures for tech interviews. Learn the exact patterns, code implementations, and LeetCode problems top companies ask.
Master the Placement Array Roadmap with this complete guide featuring curated LeetCode problems, categorized by difficulty, to help you crack technical interviews.